Basal: how an open Polish decision model was built
On 1 October basal‑1.0 was officially launched: a Polish model with open weights that returns a decision and its probability instead of a sentence. Jev, which we covered in September, does the same, but only through its vendor's API, with no weights and no paper. Basal ships with a 39‑page report that shows step by step how it was built, with a measurement behind every design decision, including the ideas that failed. On 4 October version 1.5 followed, with three models and a new hidden test that changes the comparison with Jev.
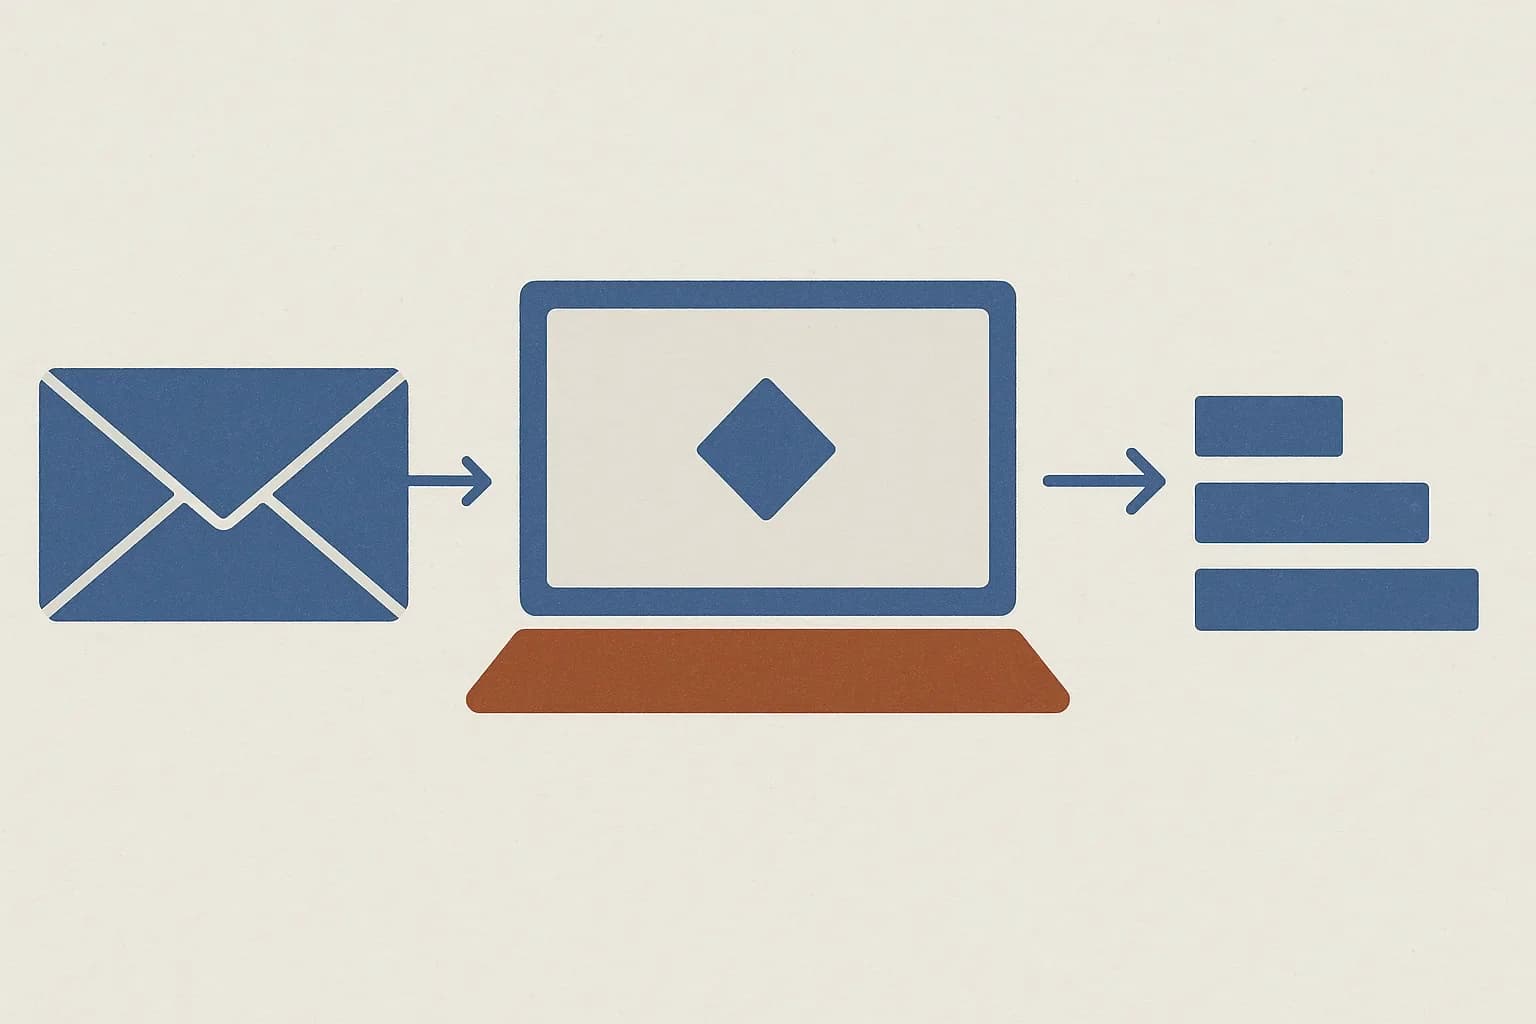
Basal works like Jev, except on your own hardware. You send the content (a message, a document or a JSON object), a question and the list of allowed answers. Back comes a probability for each answer and not one generated word. In the report's example a customer writes that they cannot log in to online banking, and out of three departments the model picks online banking support with a confidence of 0.999, in 10.5 ms on an H100 server card.
The model comes from Remigiusz Kinas, one of the five authors of the Bielik v3 Small technical report, publishing here under the affiliation ai5. The first version has two models, basal-1.0-4.5B and the smaller basal-1.0-1.5B, both fine-tuned from SpeakLeash's Bielik v3. What version 1.5 changed is covered at the end. The weights and the engine are under Apache 2.0, which permits commercial use, and the server accepts requests in Jev's format at the same endpoint, POST /v1/systemone.
The idea: read a letter, write nothing
There is no new architecture underneath. The options go to an ordinary language model as letters A to J, the start of the answer is written for it, and the decision is the probability distribution over those letters in a single pass. The ten letters set the limit: Basal takes 2 to 10 options, Jev up to 255. A question can be a choice of one option, a yes or no, or a score on a scale.
Every question is asked twice, with the options in their original and reversed order, and the results are averaged, because a language model's choice is swayed by where an answer sits in the list. Finally the confidence is calibrated separately for each question type, so that 0.9 means nine hits in ten.
First, measure where the gap really is
The work began by comparing Jev with eleven open general-purpose language models, Bielik and PLLuM among them, on a suite of 3,079 questions. The best of them trailed Jev by 12 to 13 percentage points on Polish domain knowledge, but by only 2 to 4 on decisions and reading comprehension. Calibration only looked like a gap: one rescaling number (a temperature), fitted on half the data, brought the calibration error of every open model down to about 0.05 or less. That set the ground to compete on: how many decisions can be automated at a fixed error rate. A second measurement chose the base: Bielik's Polish tokenizer, the way it cuts text into pieces, needs the fewest tokens on Polish prompts, the others tested 17 to 51% more.
Labels that can be computed
The training data was chosen so that the right answer never rests on one model's opinion. Most of it is synthetic. It comes from three sources, plus one kind of paired example.
- Computed by code: procedural deadlines with a calendar of public holidays, amounts and thresholds, rules from statutes. A generator draws the facts and a rule engine computes the answer, with no language model involved. This is 51% of the training data.
- Written by one model and checked by two others that answered without seeing the intended label. 5,613 of 15,000 cases, or 37%, passed that filter. This is 22% of the data.
- Converted from public datasets, mostly English. This is 27% of the data.
- Twin pairs: the same case with one changed fact that changes the answer. The model cannot guess from surface features of the text.
On the first version of the data, one pass (an epoch) over 15,000 examples lifted the 4.5B model's accuracy from 47.6% to over 82%, against 68.6% for Jev on that same first test. Shuffling the option order during training cut the share of answers that change when the list is reversed from 16.4% to 3.1%. The final set has 63,663 examples, and the test uses templates, statutes and domains the model never saw.
One question stayed at coin-flip level for every system: was the document filed on time? Once it was split into two simple questions, the deadline and the filing date, and the dates were compared in code, the 4.5B model on an earlier version of the data rose from 48% to 92%, and Jev from 52% to 69%. The released model answers these questions without error when they are split, and still scores 48% when asked directly.
Confidence turned into a threshold
Accuracy alone does not say how much work a model takes off people. So the report measures coverage: the share of decisions that clear a confidence threshold, below which a case goes to a person. The threshold was fixed on a separate part of the data, before testing, so that at most 1% of the accepted decisions would be wrong. The 4.5B model then settles 58.6% of 8,560 Polish and English test decisions on its own, and 1.2% of the decisions it settles are wrong. Jev under the same procedure settles 18.1%, at 0.3% error.
Speed from serving, not from the model
A decision needs no generated tokens, so its time is the time of one pass through the model. The author notes that the computation itself takes an H100 a few milliseconds, and that the 32 ms measured for a plain pass at 16‑bit precision is mostly the cost of launching thousands of small operations one by one. So the work went into how the model is served, with a check after every change that the decisions still matched the reference version.

The biggest single drop came from moving from 32‑bit to 16‑bit precision: 176.5 ms to 32.9 ms. The last step works because the two option orders differ only at the end: the content and the question are 78% of the tokens on average. The engine computes the shared start once and attaches both endings to it, so the second order costs little: 12.5 ms for both against 11.6 ms for one. On a consumer RTX 5090 the same path gives 27.3 ms, on a B300 server card 8.8 ms.
What did not work
- Distillation on general web text, meaning training a smaller model on a larger one's predictions: a pilot, stopped because Polish knowledge fell by 2 points. Only distillation on the decisions themselves worked, and it produced the 1.5B model.
- Stopping the computation early cut the time only by a factor of 1.13 to 1.16, because the decision only becomes readable in the last ten of 60 layers. It stayed in the engine as an option for the 1.0 models.
- New data with reasoning tasks: 3.9 points up on the public English benchmark, but 0.6 down on Polish decisions and 1.5 down on the general Polish set. Both losses are within one to two standard errors, but the rule had been fixed before the experiment: the new version replaces the old one only if the Polish score does not fall. The old version stayed.
The result and its limits
On 7,081 Polish test decisions basal‑1.0 4.5B reaches 88.4% accuracy, basal‑1.0 1.5B 84.9%, Jev 1.13.0 78.0%, and the best of eleven open Jev-like decision models, AutoJev‑27B, 77.9%. All of these figures were measured by the model's own author, and the report has not been peer reviewed.

- The Polish test set was produced by the same generators as the training data. The author says outright that this favours Basal.
- In the report's measurements the lead over Jev comes from dates, amounts and statutory rules. On broad business decisions such as ticket routing or urgency, Jev is ahead: 93.8% against 89.0% in the working measurements of table 10.
- The Polish knowledge gap that started the project remains: the 4.5B model scores 58% against 79% for Jev. The report advises supplying the needed facts in the request.
- The data generator had a wrong rule for the notice period in article 36 § 1 of the Polish Labour Code and mislabelled 125 items. The 1.0 weights repeat the error; the report promised a fix in a later version.
What basal‑1.5 changes
On 4 October the author released basal‑1.5: three models instead of two. The main basal-1.5 still has 4.5 billion parameters, basal-1.5-max has 11 billion and is built on Bielik PL 11B, and basal-1.5-mini has 1.5 billion and was distilled from max. All three share the same interface, prompt format and calibration procedure, and the limit is still 10 options. Training gained a reinforcement learning stage.
- Several questions about the same text in one pass: the engine processes the content once, so five questions take 37.8 ms on an H100 instead of 111.7 ms.
- New question types:
multi, which labels apply, and the experimentalact, which picks the cheapest action under the error costs you give or hands the case to a person. - The experimental
evidence, a passage of text that supports the answer, andfacts, dates and amounts computed for Polish text and appended to it. - It also runs through vLLM and SGLang, on a Mac through MLX, and through Ollama and llama.cpp.
The most important change is in measurement. On the author's sealed, non-public test of 3,000 new Polish decisions, prepared after the weights were frozen and scored once, basal‑1.5 reaches 93.1% against 87.4% for version 1.0. The 1.0 report's test set was consulted during development; this one was not.
The author also built Werdykt: a hidden test of 5,000 decisions in Polish and English across 10 categories, from rules and deadlines to long documents and contracts, with one protocol for every model. Here the picture differs from the 1.0 report. Jev scores 81.6%, the open Cygnet (12B) 78.5%, basal‑1.5‑max 77.3% and basal‑1.5 72.1%. The best API models exceed 98%, but take 2 to 5.5 seconds per decision, against 34 ms for basal‑1.5 at $0.048 per thousand decisions on a rented H100 at full load.

In the rules and deadlines category the Basal models score 30 to 35%, the open Cygnet 38% and Gemini 3.8 Flash 100%. Arithmetic still belongs in code. On the same 8,560 test decisions as the report, basal‑1.5 at the 1% error threshold settles 51% on its own and a re-run basal‑1.0 55.2% (the report gave 58.6%), but the new version is wrong less often: on 0.55% of the decisions it settles, against 0.89%.
We will describe our own test of Basal on Polish data, on version 1.5, in a separate article.
What to take from this report into your own project
- 01Before you choose a model, measure where the gap is: in knowledge, in decisions, or only in calibration. That decides whether you need a bigger model or better data.
- 02Build a test set whose labels can be computed or checked against a document. One model's opinion is not enough.
- 03For every rule, add a twin pair: one changed fact and a different correct answer.
- 04Ask a model vendor for one number: how many decisions go through without a person at 1% error, with the threshold fixed before the test.
- 05Write down the rule for when a new version replaces the old one before you run the experiment.
Sources
- 01Remigiusz Kinas, basal‑1.0: Reliable, Highly Optimized Typed Decisions for Polish (technical report)published 28 September 2026
- 02rkinas/basal, inference engine and READMErevision of 30 September 2026
- 03Hugging Face, model card Remek/basal‑1.0‑4.5Blast updated 28 September 2026
- 04Hugging Face, leaderboard Remek/jev-pl-benchmarklast updated 27 September 2026
- 05basal.si5.pl, basal‑1.0 - dynamiczny klasyfikatorpublished 1 October 2026
- 06basal.si5.pl, basal‑1.5: trzy modele, więcej możliwościpublished 4 October 2026
- 07basal.si5.pl, Werdykt benchmarkresults of 4 October 2026
- 08rkinas/basal, README of basal‑1.5revision of 4 October 2026
- 09Hugging Face, model card Remek/basal‑1.5‑maxlast updated 3 October 2026
- 10Ociepa, Flis, Kinas, Wróbel, Gwoździej, Bielik v3 Small: Technical Reportv1 5 May 2025, v2 8 May 2025